How to Deploy a Claude Agent SDK Agent to Your Own AWS or GCP Account
Run Claude Agent SDK sessions inside a TypeScript service, mirror their transcripts to Postgres, and deploy it to your own cloud with Encore.

The Claude Agent SDK gives your own code the agent loop behind Claude Code, including its tool handling and context management. Inside a script it is a single query() call. In a deployed service, each call starts a Claude Code subprocess that writes its session transcript to local disk, which a new container no longer has.
This guide builds a small notes agent with @anthropic-ai/claude-agent-sdk 0.3 inside an Encore service. The agent gets two MCP tools backed by Postgres and no built-in tools, its sessions are mirrored to Postgres so a thread can continue on any instance, and the Anthropic key lives in a secret.
What you will build
One service called agent with three endpoints:
POST /threadscreates a thread.POST /threads/:id/messagesruns a turn, resuming the thread's Claude session if it has one.GET /threads/:idreturns the turns with their replies.
The two tools, save_note and search_notes, read and write a notes table. The same shape is used in the Cursor Agents example, which this guide adapts to the Claude Agent SDK.
Why self-host the agent backend
Hosted agent platforms run the loop, keep the session and give you a dashboard. Running the Claude Agent SDK in your own service makes sense when the agent needs data that already lives in your database, when transcripts should stay in an account you control, or when the agent is one feature inside a backend that has its own users and permissions.
The cost is that you run what the platform would have run: storage for sessions, a key the service can read, an HTTP layer and a deploy target. The model calls still go to Anthropic. What moves into your account is the session history, the tool code and the data the tools touch, which is often the part a security review cares about.
Set up the project
You need Node 18.14 or newer (the SDK's engines field), Docker for the local database, and the Encore CLI. Install the CLI with the command for your operating system below, then create the app, selecting Empty app as the template when prompted. The new app already has encore.app, package.json with encore.dev and a tsconfig.json, so you only add the agent packages:
Run in your terminal to get started locally.
The service definition is a single file:
// agent/encore.service.ts
import { Service } from "encore.dev/service";

export default new Service("agent");
The agent also needs a database for its state and a secret for the API key, which is where Encore comes in.
How Encore provisions the database and secret
Encore combines an open source infrastructure SDK for TypeScript and Go with a platform that provisions and deploys into your own AWS or GCP account. The database and the API key are declared in the service code, encore run starts Postgres locally with the migrations applied, and a deploy creates the same resources in your cloud.
That matters for agent code because the session store, the tools and the tables they use all change together. If you work with an AI coding agent, it can read the database declaration and the migrations in the same files it edits, so a new tool and the table behind it arrive as one reviewable diff.
Add the database
Besides threads, turns and notes, the migration has a session_entries table for SDK transcripts. Entries usually carry a uuid, and the SDK asks stores to treat it as an idempotency key, which the partial unique index handles.
-- agent/migrations/1_create_tables.up.sql
CREATE TABLE threads (
    id          TEXT PRIMARY KEY,
    session_id  TEXT,
    created_at  TIMESTAMPTZ NOT NULL DEFAULT now()
);

CREATE TABLE turns (
    id          BIGSERIAL PRIMARY KEY,
    thread_id   TEXT NOT NULL REFERENCES threads(id) ON DELETE CASCADE,
    prompt      TEXT NOT NULL,
    reply       TEXT,
    status      TEXT NOT NULL,
    cost_usd    DOUBLE PRECISION,
    created_at  TIMESTAMPTZ NOT NULL DEFAULT now()
);

CREATE TABLE notes (
    id          BIGSERIAL PRIMARY KEY,
    title       TEXT NOT NULL,
    body        TEXT NOT NULL,
    created_at  TIMESTAMPTZ NOT NULL DEFAULT now()
);

-- Claude Agent SDK transcripts, mirrored through the sessionStore option.
CREATE TABLE session_entries (
    seq          BIGSERIAL PRIMARY KEY,
    project_key  TEXT NOT NULL,
    session_id   TEXT NOT NULL,
    subpath      TEXT NOT NULL DEFAULT '',
    uuid         TEXT,
    entry        JSONB NOT NULL
);
CREATE INDEX session_entries_key ON session_entries (project_key, session_id, subpath, seq);
CREATE UNIQUE INDEX session_entries_uuid ON session_entries (project_key, session_id, subpath, uuid)
    WHERE uuid IS NOT NULL;
The database is declared in one line, and Encore applies the migrations in ./migrations when encore run starts and on each deploy. The database docs cover the details.
// agent/db.ts
import { SQLDatabase } from "encore.dev/storage/sqldb";

export const db = new SQLDatabase("agent", { migrations: "./migrations" });
Store sessions in Postgres
The session storage docs describe the SessionStore interface. The SDK still writes the transcript locally, then calls append with batches of entries, and on resume it calls load once and replays the entries from a temporary file. Only append and load are required. The option is marked alpha in the SDK's types, so check the changelog when you upgrade.
// agent/store.ts
import type { SessionStore, SessionStoreEntry } from "@anthropic-ai/claude-agent-sdk";
import { db } from "./db";

// Keeps Claude Agent SDK transcripts in Postgres, so any instance of the
// service can resume any session after a deploy or restart.
export const postgresSessionStore: SessionStore = {
  async append({ projectKey, sessionId, subpath = "" }, entries) {
    for (const entry of entries) {
      await db.exec`
        INSERT INTO session_entries (project_key, session_id, subpath, uuid, entry)
        VALUES (${projectKey}, ${sessionId}, ${subpath}, ${entry.uuid ?? null},
                ${JSON.stringify(entry)}::text::jsonb)
        ON CONFLICT DO NOTHING`;
    }
  },
  async load({ projectKey, sessionId, subpath = "" }) {
    const entries: SessionStoreEntry[] = [];
    for await (const row of db.query<{ entry: SessionStoreEntry | string }>`
      SELECT entry FROM session_entries
      WHERE project_key = ${projectKey} AND session_id = ${sessionId} AND subpath = ${subpath}
      ORDER BY seq`) {
      entries.push(typeof row.entry === "string" ? JSON.parse(row.entry) : row.entry);
    }
    return entries.length > 0 ? entries : null;
  },
};
Define the tools
Tools are defined with tool() and a Zod shape, then grouped into an in-process MCP server with createSdkMcpServer. Handlers return MCP content blocks, so the results are serialized to text. The custom tools docs cover annotations and error results.
// agent/tools.ts
import { createSdkMcpServer, tool } from "@anthropic-ai/claude-agent-sdk";
import { z } from "zod";
import { db } from "./db";

const text = (value: unknown) => ({
  content: [{ type: "text" as const, text: JSON.stringify(value) }],
});

export const notesServer = createSdkMcpServer({
  name: "notes",
  version: "1.0.0",
  tools: [
    tool(
      "save_note",
      "Save a note with a short title and a body.",
      { title: z.string(), body: z.string() },
      async ({ title, body }) => {
        const row = await db.queryRow<{ id: number }>`
          INSERT INTO notes (title, body) VALUES (${title}, ${body}) RETURNING id`;
        return text({ saved: row!.id });
      },
    ),
    tool(
      "search_notes",
      "Find notes whose title or body contains the given text.",
      { query: z.string() },
      async ({ query }) => {
        const pattern = `%${query}%`;
        const notes = [];
        for await (const n of db.query`
          SELECT id, title, body FROM notes
          WHERE title ILIKE ${pattern} OR body ILIKE ${pattern}
          ORDER BY id DESC LIMIT 20`) {
          notes.push(n);
        }
        return text({ notes });
      },
    ),
  ],
});
Write the endpoints
The key comes from an Encore secret and reaches the Claude Code subprocess through env. The SDK documents that env replaces the subprocess environment instead of merging with it, which is why it spreads process.env first. CLAUDE_CONFIG_DIR points the local transcript copy at /tmp, since the durable copy is in Postgres.
// agent/api.ts
import { randomUUID } from "node:crypto";
import { query } from "@anthropic-ai/claude-agent-sdk";
import { api, APIError, type Header } from "encore.dev/api";
import { secret } from "encore.dev/config";
import { db } from "./db";
import { postgresSessionStore } from "./store";
import { notesServer } from "./tools";

const anthropicApiKey = secret("AnthropicApiKey");

const SYSTEM_PROMPT = `You keep the user's notes with the save_note and search_notes tools.
Search before answering a question about notes, and never make up a note.`;

export const createThread = api(
  { expose: true, method: "POST", path: "/threads" },
  async (): Promise<{ id: string }> => {
    const id = randomUUID();
    await db.exec`INSERT INTO threads (id) VALUES (${id})`;
    return { id };
  },
);

interface SendRequest {
  id: string;
  prompt: string;
  // Optional per-user key. Without it, the app's own key is used.
  userKey?: Header<"X-Anthropic-Key">;
}

interface SendResponse {
  status: string;
  reply: string | null;
}

export const send = api(
  { expose: true, method: "POST", path: "/threads/:id/messages" },
  async ({ id, prompt, userKey }: SendRequest): Promise<SendResponse> => {
    const thread = await db.queryRow<{ sessionId: string | null }>`
      SELECT session_id AS "sessionId" FROM threads WHERE id = ${id}`;
    if (!thread) throw APIError.notFound("thread not found");

    let sessionId = thread.sessionId;
    let status = "error";
    let reply: string | null = null;
    let cost: number | null = null;

    try {
      for await (const message of query({
        prompt,
        options: {
          model: "sonnet",
          systemPrompt: SYSTEM_PROMPT,
          tools: [], // no built-in tools: no shell, no file access
          mcpServers: { notes: notesServer },
          allowedTools: ["mcp__notes__save_note", "mcp__notes__search_notes"],
          maxTurns: 8,
          resume: sessionId ?? undefined,
          sessionStore: postgresSessionStore,
          env: {
            ...process.env,
            ANTHROPIC_API_KEY: userKey || anthropicApiKey(),
            CLAUDE_CONFIG_DIR: "/tmp/claude",
          },
        },
      })) {
        if (message.type === "system" && message.subtype === "init") {
          sessionId = message.session_id;
        }
        if (message.type === "result") {
          status = message.subtype;
          reply = message.subtype === "success" ? message.result : null;
          cost = message.total_cost_usd;
        }
      }
    } catch (err) {
      status = "error";
      reply = err instanceof Error ? err.message : String(err);
    }

    await db.exec`UPDATE threads SET session_id = ${sessionId} WHERE id = ${id}`;
    await db.exec`
      INSERT INTO turns (thread_id, prompt, reply, status, cost_usd)
      VALUES (${id}, ${prompt}, ${reply}, ${status}, ${cost})`;
    return { status, reply };
  },
);

interface Turn {
  prompt: string;
  reply: string | null;
  status: string;
  createdAt: Date;
}

export const history = api(
  { expose: true, method: "GET", path: "/threads/:id" },
  async ({ id }: { id: string }): Promise<{ turns: Turn[] }> => {
    const turns: Turn[] = [];
    for await (const t of db.query<Turn>`
      SELECT prompt, reply, status, created_at AS "createdAt"
      FROM turns WHERE thread_id = ${id} ORDER BY id`) {
      turns.push(t);
    }
    return { turns };
  },
);
tools: [] removes every built-in tool, so the agent has no shell and no file access, and allowedTools lets the two MCP tools run without a permission prompt. query() returns an async iterator of messages: the system message with subtype init carries the session id, and the final result message carries the reply and the cost. Errors are recorded as a turn instead of failing the request, so the history shows what went wrong.
How state and resume work
The Claude Agent SDK identifies a conversation by its session id, which arrives in the system init message of the first turn. The endpoint saves that id on the thread. On the next turn it passes the id as resume, and the SDK calls load on the store, writes the entries to a temporary transcript and continues from there. New entries from the turn come back through append.
The store writes with ON CONFLICT DO NOTHING on the entry's uuid, because the SDK may send an entry again after a retry. Entries are loaded in insertion order, which is the order the SDK expects when it replays them.
The app's own turns table sits beside the session entries. It stores the prompt, the final reply, the status and the cost in a shape the API controls, so the history endpoint never has to parse the SDK's transcript format.
API key per user or per app
You can pay for the model calls in two ways. With one key per app, the service owns an Anthropic key in a secret, every user's requests are billed to it, and you need your own limits per user. With one key per user, each request brings the user's key, usage lands on their account, and the service stores no key at all.
Each call to query() starts its own Claude Code subprocess with its own env, so a per-request key cannot leak into a concurrent request. The send endpoint here supports both: an optional X-Anthropic-Key header, declared with Encore's Header type, wins over the secret when it is present. Drop the secret if every user brings a key, or drop the header if none of them should. Either way, do not log the header, and do not store a user's key in the threads table.
Run it locally
Set the API key for your local and development environments with the Encore CLI, which prompts for the value:
Encore stores this value and syncs it to everyone working on the app, so use a personal development key, or override it for your machine only in a .secrets.local.cue file in the app root, next to encore.app.
encore run starts Postgres locally, applies the migration and serves the API on port 4000:
The second message resumes the session from Postgres. Restarting encore run between the two calls is a quick way to check that resume does not depend on files from the first process. The SDK marks sessionStore as alpha, so its behavior may change between releases.
Observability in local development
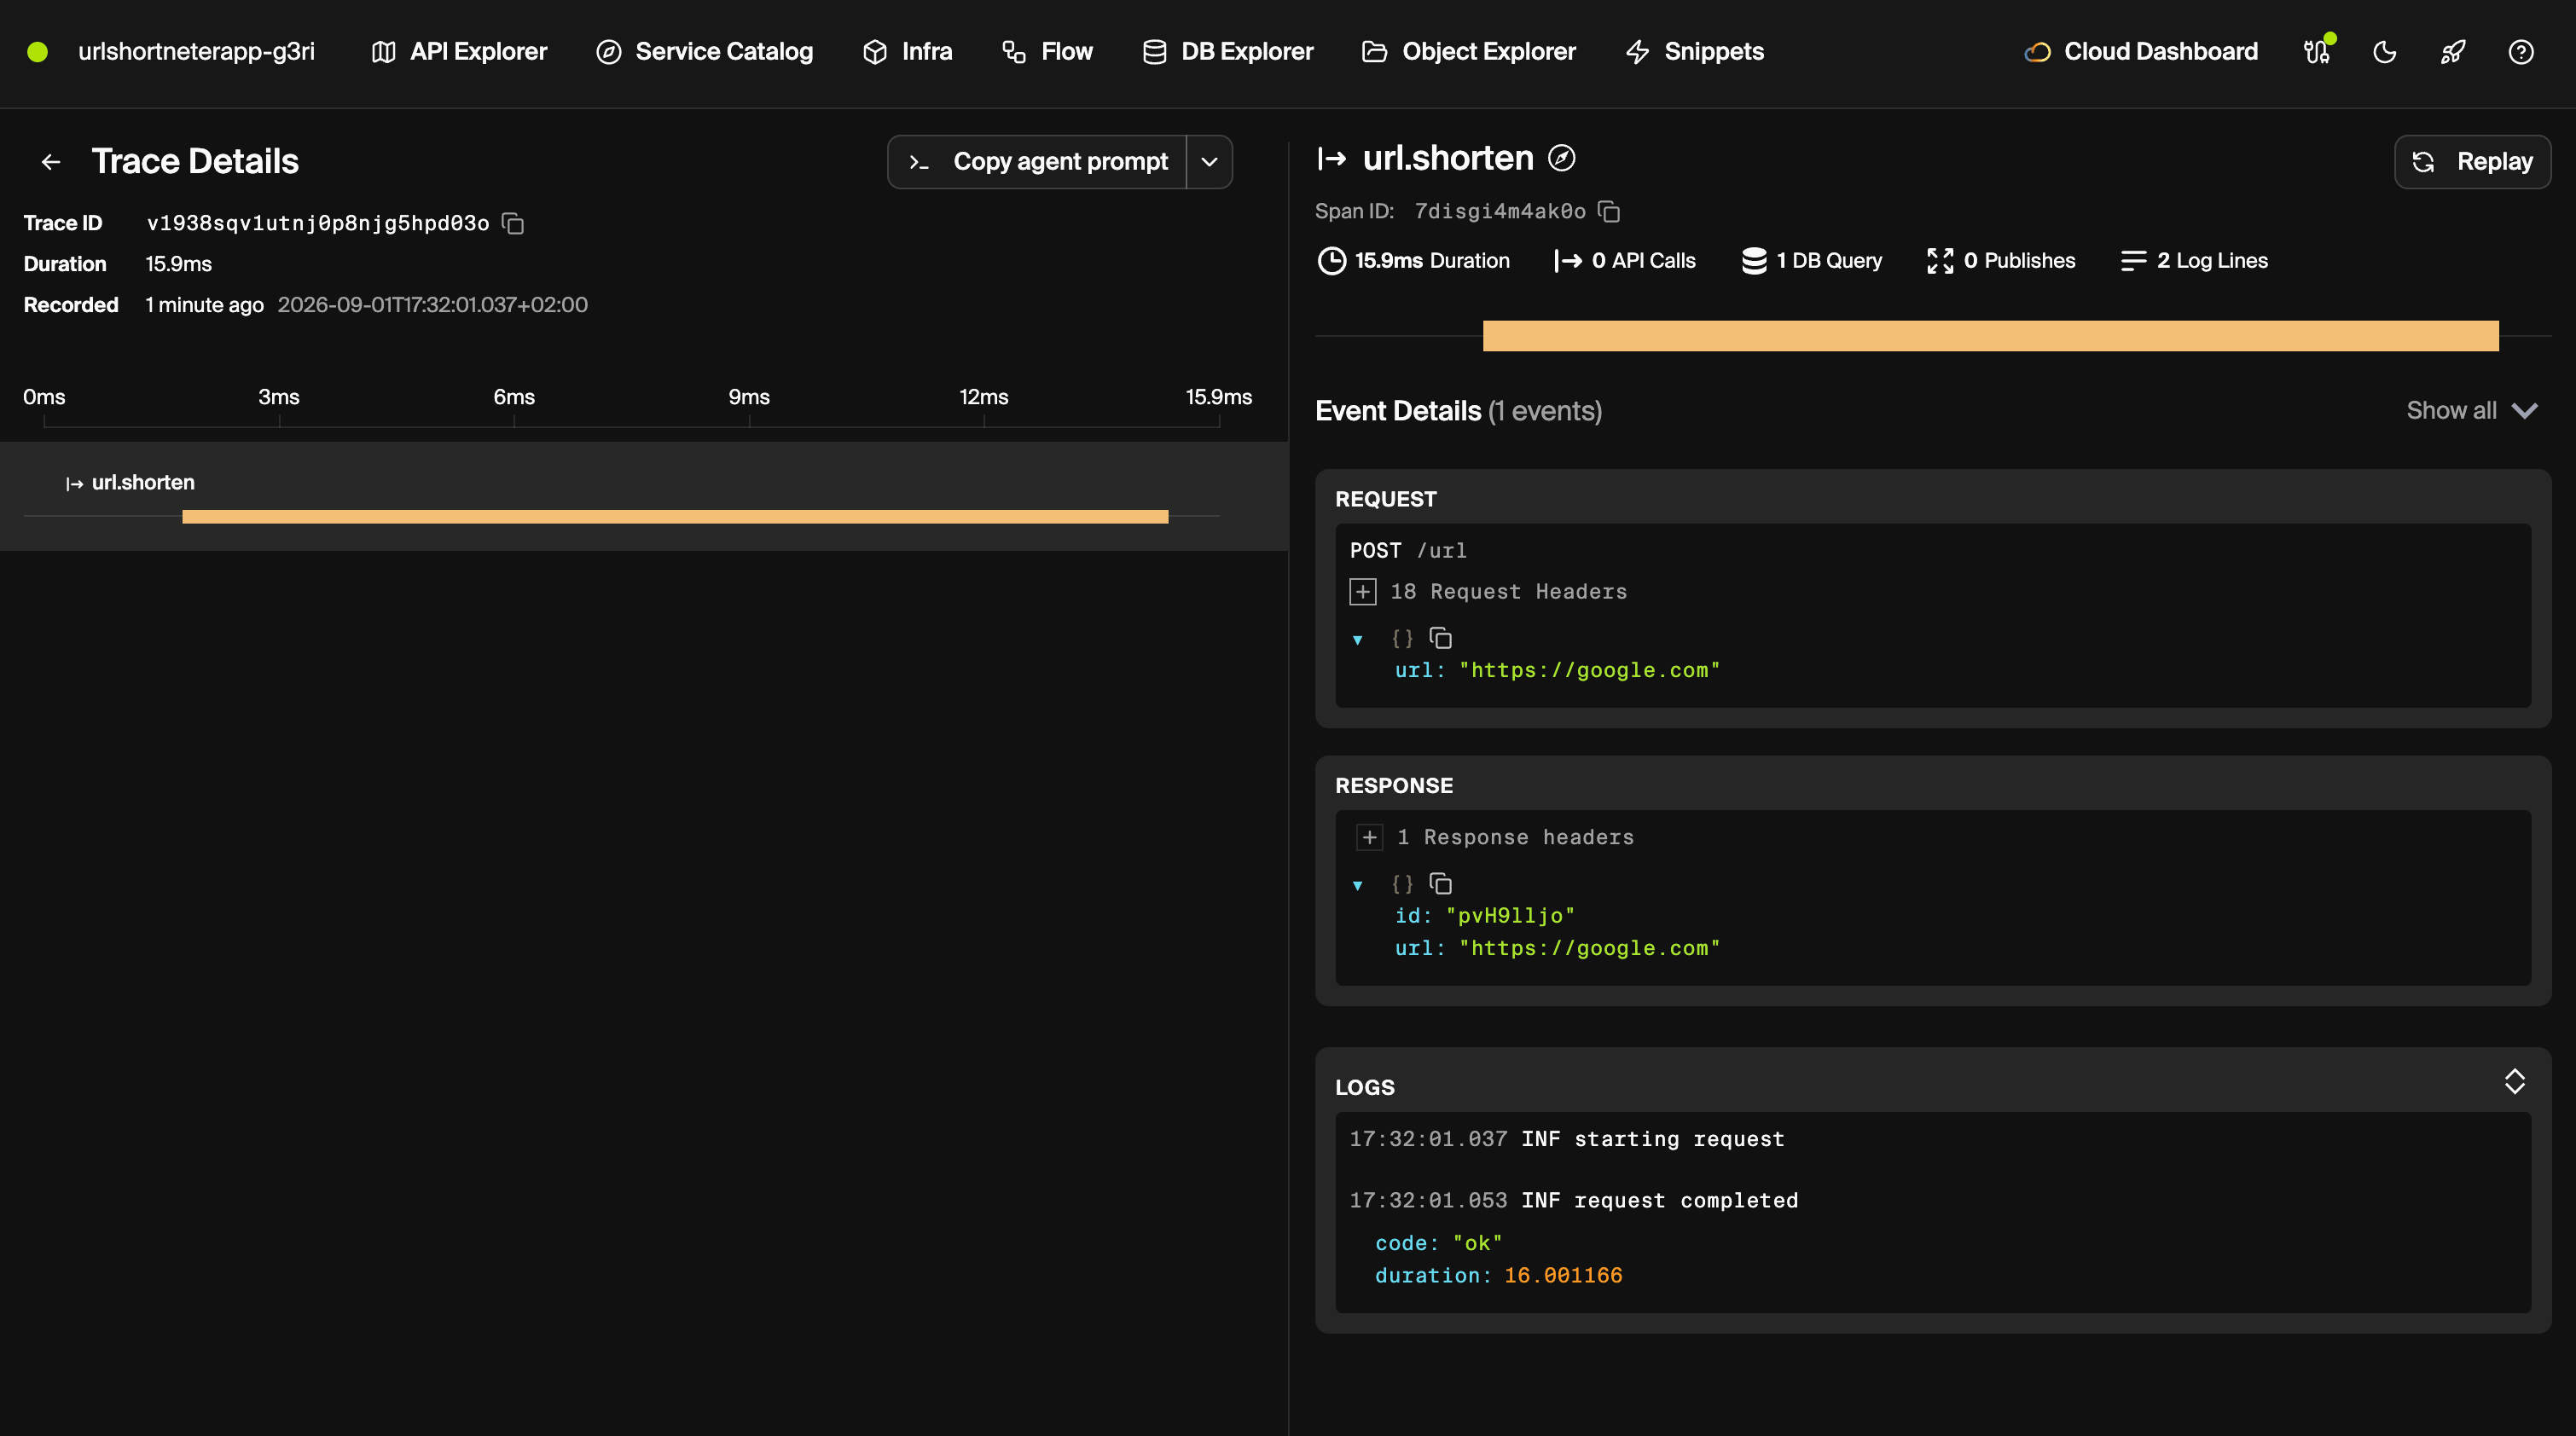
encore run prints a URL on localhost:9400 that serves the Encore Development Dashboard, and it logs a trace id with every request it serves. According to Encore's tracing docs, traces are captured automatically in local development as well as in deployed environments, and include API calls, database queries and structured logs. For an agent, the database queries are the useful part: they show whether a turn called search_notes or answered from nothing.
Deploy to your own AWS or GCP account
In the Encore dashboard, connect your AWS or GCP account and create an environment on it. Each environment gets its own database and secret values.

When the environment is created, Encore provisions what the code declares. For this app, that is one Postgres database for the agent service and one secret: RDS and Secrets Manager on AWS, Cloud SQL and Secret Manager on GCP. Encore provisions an IAM role for the service. The service runs as a container built on Encore's default base image for TypeScript apps, node:24-trixie.
Each turn spawns a Claude Code subprocess, so give the service enough memory for one subprocess per concurrent request, and add an auth handler before exposing the endpoints publicly.
Related guides
Frequently asked questions
How do I deploy a Claude Agent SDK agent to AWS or GCP?
You build a TypeScript API that runs a Claude Agent SDK agent and stores its sessions in Postgres, so a conversation can resume after a restart. It runs in your own AWS or GCP account, and Encore provisions the database and the API key secret there when you push.
Where does the Claude Agent SDK store sessions?
By default each session is a JSONL transcript under the Claude config directory on local disk. The sessionStore option mirrors those entries to a store you implement, and resume loads them back, so another host can continue the session.
How do I stop a Claude Agent SDK agent from using the shell?
Pass tools: [] to remove all built-in tools, then list only your own MCP tools in allowedTools. Custom tools are named mcp__<server>__<tool>, for example mcp__notes__save_note.
Does the env option add to process.env?
No. The SDK documents that env replaces the subprocess environment entirely, so spread process.env yourself if the subprocess needs PATH or HOME.
How do I resume a Claude Agent SDK session in a later request?
Save the session_id from the system init message of the first turn, then pass it as the resume option to query() on the next turn. With a sessionStore configured, the SDK loads the earlier entries from the store, so the next turn can run on a different instance.
Deploy to your cloud on AWS and Google Cloud
without managing infrastructure
Encore lets developers and agents define application infrastructure directly in code, then automatically provisions it from local development to production in your AWS or GCP account.
