What Is TimescaleDB?
Store sensor readings in PostgreSQL and query them with TimescaleDB.
TimescaleDB is a PostgreSQL extension for working with data collected over time. A temperature sensor might send a reading every minute, with each row recording the device, timestamp, and measured value. Collect those readings from thousands of devices for several years, and the application needs to query a growing history while new records keep arriving.
PostgreSQL can already store that data. TimescaleDB adds ways to partition it by time, calculate summaries, and manage older readings while keeping SQL and PostgreSQL clients. We'll use a small sensor dataset to show how those features work.
How TimescaleDB organizes time-series data
A time-series query usually asks about a particular period: the last hour of readings from a device, or its average temperature for each day of the month. TimescaleDB organizes records into hypertables, which look like ordinary tables when you insert or query data.
Underneath a hypertable, records are divided into chunks. With a one-day chunk interval, readings from different days go into different chunks. A query restricted to one day can skip chunks outside that period, and old chunks can be removed together when their data is no longer needed.
The hypertable documentation explains how chunks work. The SQL still names the hypertable; the application does not have to choose a chunk for each insert.
Set up the example database
Use PostgreSQL with TimescaleDB Community Edition 2.21 or later, or a Tiger Cloud service. The examples use the tsdb.columnstore table option introduced in 2.21. Continuous aggregates require the Community Edition features described in the edition comparison. Follow the installation guide to choose compatible PostgreSQL and TimescaleDB versions.
Connect with psql or another PostgreSQL client. In a new example database, enable the extension and set the session timezone:
CREATE EXTENSION IF NOT EXISTS timescaledb;
SET TIME ZONE 'UTC';

SELECT extversion
FROM pg_extension
WHERE extname = 'timescaledb';
CREATE EXTENSION enables an extension already installed on the server. It does not download TimescaleDB. The timezone setting keeps the displayed timestamps consistent with the results below.
Create a hypertable
Each reading records a temperature and battery level for one device:
CREATE TABLE readings (
  recorded_at timestamptz NOT NULL,
  device_id text NOT NULL,
  temperature double precision NOT NULL,
  battery double precision,
  PRIMARY KEY (device_id, recorded_at)
) WITH (
  tsdb.hypertable,
  tsdb.partition_column = 'recorded_at',
  tsdb.chunk_interval = '1 day',
  tsdb.columnstore = false
);
recorded_at determines which chunk receives a row. The primary key includes that time column, as required for a unique constraint on this hypertable. It also prevents two readings from the same device at exactly the same timestamp.
Columnstore is disabled explicitly for this example so the table stays in row storage while you work through it. The table creation reference describes the options and defaults. We'll cover columnar storage after the queries.
Insert sensor readings
Insert three readings from the same device. Battery values are fractions, so 0.90 represents 90 percent:
INSERT INTO readings (recorded_at, device_id, temperature, battery)
VALUES
  ('2026-10-12 10:01:00+00', 'sensor-1', 20.0, 0.90),
  ('2026-10-12 10:08:00+00', 'sensor-1', 22.0, 0.89),
  ('2026-10-12 10:16:00+00', 'sensor-1', 24.0, 0.88);
These are normal SQL inserts. An ingestion service can use the same PostgreSQL driver it would use for another table.
Group readings into time intervals
A dashboard may need a point every 15 minutes instead of displaying every individual reading. time_bucket assigns each timestamp to an interval, which you can use in a GROUP BY query:
SELECT
  time_bucket('15 minutes', recorded_at) AS bucket,
  device_id,
  avg(temperature) AS avg_temperature,
  min(battery) AS min_battery
FROM readings
WHERE recorded_at >= '2026-10-12 10:00:00+00'
  AND recorded_at < '2026-10-12 11:00:00+00'
GROUP BY bucket, device_id
ORDER BY bucket;
The first two readings fall into the 10:00 bucket. Their temperatures average to 21, and the lowest battery reading is 0.89. The third reading falls into the next bucket:
The fixed dates make the example repeatable. A live dashboard would usually supply a time range selected by the user or a rolling window.
Device details can remain in an ordinary PostgreSQL table. You can join the readings to that table to show a device's location or owner alongside its measurements.
Keep hourly summaries with continuous aggregates
The query above calculates its result from the readings each time it runs. For a dashboard repeatedly querying a large history, a continuous aggregate stores a summary and refreshes it incrementally.
Create an hourly summary using the same aggregate functions:
CREATE MATERIALIZED VIEW hourly_device_readings
WITH (
  timescaledb.continuous,
  timescaledb.materialized_only = true
) AS
SELECT
  time_bucket('1 hour', recorded_at) AS bucket,
  device_id,
  avg(temperature) AS avg_temperature,
  min(battery) AS min_battery
FROM readings
GROUP BY bucket, device_id
WITH NO DATA;
WITH NO DATA creates the view without immediately calculating its contents. Refresh the hour containing the sample readings, then query it:
CALL refresh_continuous_aggregate(
  'hourly_device_readings',
  '2026-10-12 10:00:00+00'::timestamptz,
  '2026-10-12 11:00:00+00'::timestamptz
);

SELECT *
FROM hourly_device_readings
ORDER BY bucket, device_id;
All three readings belong to the same hour, so this produces one row with an average temperature of 22 and a minimum battery level of 0.88.
For ongoing ingestion, add a scheduled refresh:
SELECT add_continuous_aggregate_policy(
  'hourly_device_readings',
  start_offset => interval '30 days',
  end_offset => interval '1 hour',
  schedule_interval => interval '15 minutes'
);
Every 15 minutes, the policy refreshes complete hourly buckets within a window from 30 days ago to one hour ago. That window allows recent readings to be corrected or arrive late. Older history needs a manual refresh, as we used for the sample data.
The view is explicitly configured to return materialized results only. TimescaleDB also supports real-time aggregates that combine stored summaries with recent raw readings. The continuous aggregate guide covers creation, and the refresh guide explains how to choose the window.
Store and remove older readings
Yesterday's readings may be queried individually when investigating a device. A year's history may mostly be used for reports. TimescaleDB's Hypercore storage supports row and columnar storage, so older chunks can be converted to a compressed columnar format while recent data remains in rows.
Our example disabled columnstore to keep the initial setup explicit. For a production table, you can enable it and configure a policy to convert older chunks. The columnstore policy reference describes the setup; automatic policy creation differs between versions.
Retention is a separate decision. You might keep individual readings for 90 days and hourly summaries for a year. A retention policy drops entire expired chunks, avoiding a row-by-row deletion of the raw history.
If you keep summaries after deleting the readings, their refresh window must exclude the deleted period. Refreshing a summary over a period whose raw data has been removed can remove the summary too. The retention guide explains how to coordinate the two policies.
Running TimescaleDB
Tiger Cloud provides a managed PostgreSQL service with TimescaleDB. You create the database service and connect the application, while the provider operates the database infrastructure. This avoids installing and upgrading the extension on your own server.
You can also install TimescaleDB on PostgreSQL infrastructure you operate. That gives you control over the server and extension versions, with database upgrades and recovery handled by your team. For local development, a separate TimescaleDB instance lets you test the same queries and schema without writing to production.
Building the application with Encore
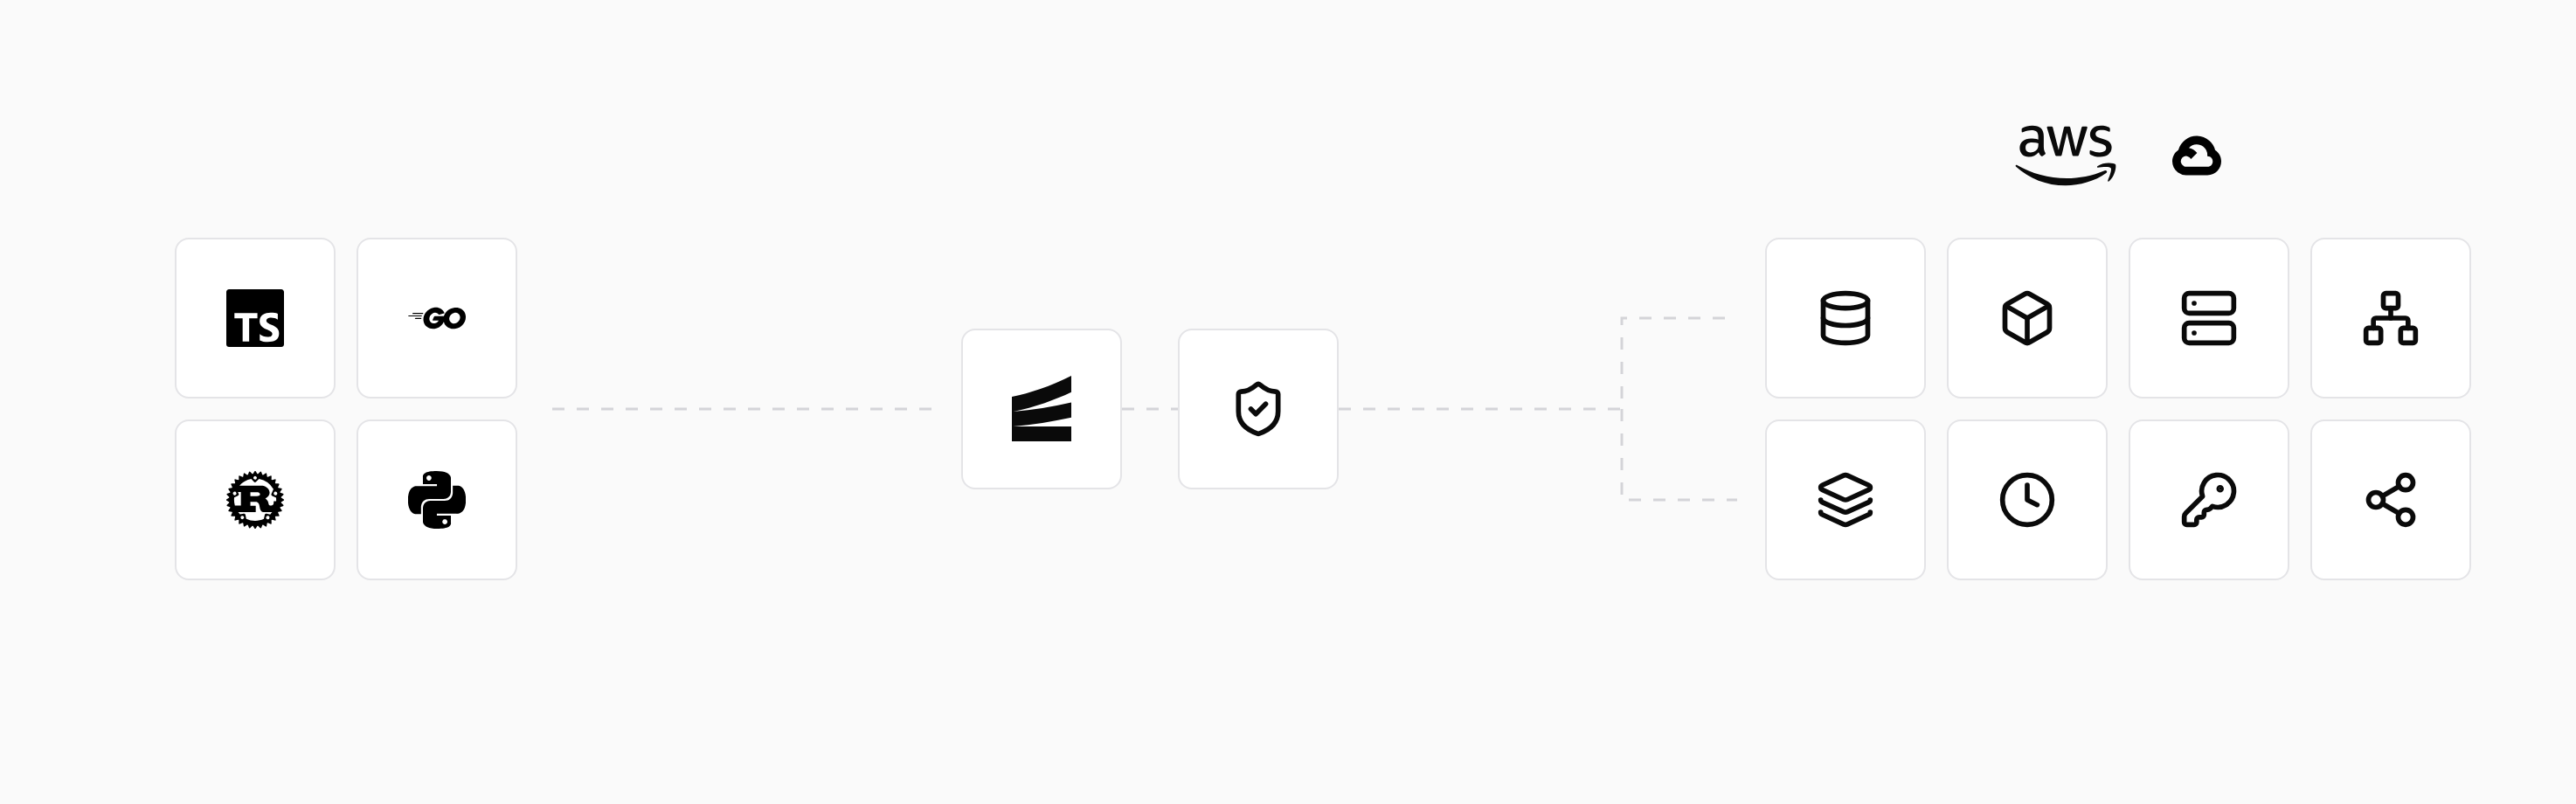
TimescaleDB stores the readings, while the application decides who can submit them and which devices a user can see. With Encore, you can build those services and deploy the backend in your own AWS or GCP account through a Git-based workflow.
The service connects to TimescaleDB using a PostgreSQL client. Keep the connection credentials in secrets and allow network access from the deployed environment. Encore provisions other resources declared in the application, such as a topic for processing incoming readings; the TimescaleDB instance is operated separately by you or its hosting provider.
Install pg with npm install pg and its TypeScript definitions with npm install --save-dev @types/pg. Set the TimescaleDatabaseURL secret to your database connection URL. The example requires TLS and verifies the server certificate and hostname. For a private certificate authority, supply its CA certificate through sslrootcert in the URL; the file must be available to the service. A helper in an Encore TypeScript service can then query the readings:
import { secret } from "encore.dev/config";
import { Pool } from "pg";

const timescaleURL = secret("TimescaleDatabaseURL");
const url = new URL(timescaleURL());
url.searchParams.set("sslmode", "verify-full");
const timescale = new Pool({
  connectionString: url.toString(),
  connectionTimeoutMillis: 5_000,
  query_timeout: 10_000,
});

export async function temperatures(deviceID: string, since: Date) {
  const { rows } = await timescale.query(
    `SELECT time_bucket('15 minutes', recorded_at) AS bucket,
            avg(temperature) AS temperature
     FROM readings
     WHERE device_id = $1 AND recorded_at >= $2
     GROUP BY bucket ORDER BY bucket`,
    [deviceID, since],
  );
  return rows;
}
For the sample data, call temperatures("sensor-1", new Date("2026-10-12T10:00:00Z")). It returns the two 15-minute averages shown earlier. The device ID and starting time are passed as query parameters through the PostgreSQL client.
For local tests, point the service at a separate TLS-enabled TimescaleDB database with the same extension and schema. Encore starts the application's other declared local resources. A plain PostgreSQL test database cannot exercise the hypertable and continuous aggregate behavior shown here without the TimescaleDB extension.
Run in your terminal to get started locally.
Related guides
Frequently asked questions
What is TimescaleDB?
TimescaleDB is a PostgreSQL extension for time-series data. It partitions timestamped records into chunks and adds functions for querying time intervals, maintaining summaries, and managing older data.
Is TimescaleDB a separate database from PostgreSQL?
No. It runs as an extension inside PostgreSQL, so applications can use PostgreSQL drivers and SQL. The server must have the extension installed, and it must be enabled in the database.
When should I use TimescaleDB?
Consider it when your application continually collects timestamped records and queries them by time range, such as sensor readings or application metrics. Hypertables and continuous aggregates help manage growing histories. A timestamp column alone does not mean you need TimescaleDB; an indexed PostgreSQL table may already handle the workload.
Can I test an application that uses TimescaleDB locally?
Yes. Run a separate TimescaleDB instance for development and tests, with the extension and schema the application needs. An Encore service can connect to that instance through a PostgreSQL client while Encore supplies its other declared local resources.
Deploy to your cloud on AWS and Google Cloud
without managing infrastructure
Encore lets developers and agents define application infrastructure directly in code, then automatically provisions it from local development to production in your AWS or GCP account.
